Showing posts with label round robins. Show all posts

Monday, June 9, 2014

Resolving ties in a round-robin tournament

Let's consider a round-robin tournament. Arrows point to the loser in each match.


A is 4-1; B, C, and D are 3-2; E is 2-3, and F is 0-5. How to break the three-way tie for second place? Most round-robin tournaments would use total speaker points, but I think this is unnecessary. (And all sorts of weird things can happen if you use total points to decide tournaments.)

There are four different methods I would like to consider. The first is a method of my own invention, weighted wins and weighted losses. While this method is very simple and easy to use, it is better for incomplete tournaments (regular tournaments) than it is for a complete tournament (a round robin). One key bias to note is that the method will prefer multiple smaller upsets than one big upset. In the running example, the weighted wins will rank the teams {A, B, C-D tie, E, F}. This means C's win over A, D's win over B, and E's win over D are all ties.

The second method and third methods both require using the point differentials to order the teams. I invented the following differentials in speaker points:


The second method is the ranked pairs method. The wins are ranked in order of margin, in this case, speaker point differentials. (Let's say the speaker points are adjusted by each judge's typical points. For example, a differential of 4 speaker points might be nudged up to 4.1 if 4 is actually quite a large point differential for that judge. Low point wins could be entered as zeros or a small positive number, and they should not be entered as negative numbers.)

This means the wins go A over F, A - E, B - F, D - F, D - C, C - E, A - D, C - F, B - C, B - E, A - B, D - B, E - F, C - A, and E - D. One applies the wins in order. Wins that create a contradiction (a cycle) are ignored. For example, the first win, A over F, is applied first:

{A, F} {B, C, D, E unranked}

Then next A over E:

{A, E-F tie} {B, C, D unranked}

And so on. In this particular tournament, one does not reach a contradiction until the last two wins, so one ignores C over A (A beat B, B beat C, so acknowledging C beat A would create a cycle). Same thing for E over D. Without these two results, A has 4 wins and 0 losses, B has 3 wins and 2 losses, C has 2 wins and 2 losses, D has 3 wins and 1 loss, E has 2 wins and 3 losses, and F has 0 wins and 5 losses. This sets up the ranking: {A, D, B, C, E, F}.

The third method is the Schulze method. The key idea is to look at the strongest path from each team to each opponent. The path may go through intermediaries, but it has to follow the directions of wins. For example, if a team is undefeated, no opponent would have any path back to that team, so all entries to the undefeated team would be scored zero. The strongest path is scored by its weakest link. In our running example, every path to A would go through C, so the paths would all have a strength of 1.1, for the weakest link, C over A.

Here is the path strength matrix, with the strongest of each pair (e.g., A over B vs. B over A) highlighted:
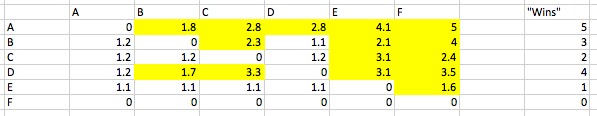

As you can see, A emerges the overall winner. The path from A to C is stronger than the path from C to A, even though the latter was an actual win, whereas the former is a pathway through D. The final ranking with the Schulze method would be {A, D, B, C, E, F} again.

The final method I would like to look at is a modified version of the Kemeny-Young method. First, one would generate a list of every possible ranking consistent with the results. Since the original tournament generated a three-way tie between B, C, and D, the possible rankings are:

{A, B, C, D, E, F}
{A, B, D, C, E, F}
{A, C, B, D, E, F}
{A, C, D, B, E, F}
{A, D, B, C, E, F}
{A, D, C, B, E, F}

Then, each ranking is scored, and the highest score ranking is preferred. (Earlier, I looked at minimizing upsets, but the effect is exactly the same.) The highest score ranking is 13:


Two results are "upsets": C over A and E over D. But this ranking is consistent with all the other results, thus earning the highest score.

To avoid ties, one could modify the wins by including decimal values for point differentials and judge variance. For example, A's win over D could be given a score of 1.028 (the 0.028 for the point differential in that win), whereas A's win over F could be given a score of 1.05. Adding tiny decimal values will not change how many upsets there are in the final, highest scored ranking -- the tiny decimals would never be worth enough points to offset an additional upset. All that the decimal values would do is allow one to chose between two otherwise tied rankings, i.e., two rankings with equal numbers of upsets.

Ranked pairs, Schulze, and Kemeny-Young all agree on the best ranking in my example: {A, D, B, C, E, F}. They do not have to, but they do. My weighted wins method disagrees, but I see this as a weakness of my method when applied to a round-robin tournament.

Conceptually, Kemeny-Young is the easiest method of all. It looks for the ranking that is most consistent with the actual wins and losses, and then if we want, at point differentials as a tie-breaker. It is an easy method to code. It would be easy to use this method for multiple-ballot rounds. My recommendation would be to use Kemeny-Young to break round-robin ties, not total speaker points or total judge variance.

Wednesday, January 20, 2010

Differing opponent strengths

Below is a graphic of a traditionally-run tournament.


The horizontal axis shows each team's final strength; the vertical axis shows each team's average opponent strength; the size of the bubble shows, for each team, the standard deviation of its opponents' strengths. A small bubble represents a team that debated opponents that were all very close together in strength. A large bubble represents a team that debated a wide cross-section of opponents, some weak and some strong.

I think about how a debate tournament ought to look, if it's paired fairly. It seems to me that every team ought to have a good cross-section of opponents. Thus, a fair tournament would be like a partial round robin. We would know that 3-3 teams were truly middle-of-the-pack because of their abilities, not because they got an unfair draw. The bubbles in the diagram would be bigger (each team sees a true cross-sections of opponents) and closer to the horizontal line (average opponent strength for each team would be closer to the overall average opponent strength).

It's relatively easy to pair a tournament like this, even on the fly. To pair a round, you can look at each team's opponents and decide what is missing so far. After three rounds, a team might have debated a 0-3, a 2-1, and a 3-0 opponent; they would now debate a 1-2 opponent. It is true that the opponent records change after the fourth round, but the process is repeated, and by the end, most teams will debate a decent cross-section of opponents from 0-6 to 6-0. Of course, traditional tournaments do not do this; teams debate opponents within brackets. Why?

The reason is that brackets increase the accuracy of rankings. Consider a 4-2 team. Does it deserve to break? If the tournament pairs it against a representative cross-section, this team would debate a 6-0 opponent, a 5-1, a 4-2, a 3-3, etc. There's only one opponent with an equal record -- but it's precisely the comparisons to very similarly-abled opponents that shed the most accurate information about a team's true strength. In a brackets system, the same team would likely debate several 4-2 opponents. There are more points of comparison, allowing for finer rankings. The downside, though, is that a team could go through the preliminary rounds of the tournament debating opponents that are all at exactly the same level. It seems to me like something valuable would be lost.

Of course, these two virtues -- fairness and accuracy -- trade off. You can't maximize both. But there are several ways to get a reasonable equilibrium. For example, pair odd rounds to have every team debate a reasonable cross-section of opponents (i.e., across brackets), and pair even rounds to increase accuracy of rankings (i.e., within brackets).

Tuesday, August 4, 2009

Network graph theory and debate tournaments

I recently saw A Numbers Game's charts of debate tournaments, which look like modified network graphs, and it inspired me to post about some thoughts I'd had a few years ago about graph theory and debate tournaments. (Network) graph theory is a fascinating branch of mathematics, and it is directly applicable to debate tournaments. Basically, a network graph is anything that maps all the pathways (edges) between some nodes (vertices). A network graph of a debate tournament shows the match-ups (edges) between the teams at the tournament (vertices). An edge without an arrow would just show a match-up between two teams; an edge with an arrow would indicate the winner of it. A network graph can show the results of all six (or eight or whatever) preliminary rounds simultaneously. You can see a lot of interesting patterns that would be hard to notice any other way; I've used network graphs as a way to illustrate how a tournament played out.

You might think, since graphs are a complete mapping of all the preliminary round results, that they could be used to rank all the teams at a tournament from first seed to worst. However, if you tried to use a graph this way, you'd run into three different problems. Graphs are best for illustrative purposes (and one alternative use I'll suggest at the end).

The first problem with trying to use a graph to seed the teams is that you still need a lot of tiebreakers. Here's a simple example:


As indicated by the graph, team A beat B and C, and teams B and C both beat D. The problem is that B and C can't be ranked against each other from this information alone. Given the results, the final rankings must contain the sequences {A, B, D} and {A, C, D}, but both {A, B, C, D} and {A, C, B, D} satisfy this. The problem is that, except for round robins, there will always be teams that didn't meet at the tournament, and thus, pairs of vertices without edges.

Ok, so, you still need tiebreakers, but a network graph as a ranking mechanism presents a second, bigger problem: "contradictions." Let's say we run a really small tournament, and we must force A and B to debate twice. Here's one possible outcome that creates a contradiction:


A (aff.) beat B, but B (aff.) beat A. If we try to use the network graph to rank these two teams, we'd be forced to give two contradictory statements. (It's worth remembering that a team's strength is not invariant: teams can be better on one side than the other, they can have off rounds or lucky rounds, and judges also play a factor.) This is simple enough to resolve: we can use speaker points to rank one team higher than the other. Here's a slightly more complex version of the same problem:


A beat B (rd 1), B beat C (rd 2), and C beat A (rd 3). There's a contradiction here also. It will have to be resolved by "upsetting" one result, that is, a team must be ranked below an opponent whom they beat. For example, a final ranking might be {A, B, C}, which means that C's victory over A was "upset" or "overruled" because A had more overall wins, better speaker points, etc., than B or C. Bear in mind that doing a graph didn't create this problem; it merely exposed it. We're mostly oblivious to it because cume sheets show wins, points, etc., and don't provide a network graph. Look carefully through the results of nearly any tournament, and I'd be willing to beat you can find at least a few teams who are ranked below (based on overall record, speaks, etc.) an opponent they beat. Here's another example:


Any such type of contradiction, no matter how many teams, is known as a simple cyclical graph, if there's only one cyclical pathway. The good news is that, however long a simple cyclical graph, only one result has to be upset: {A, B, C, D} only upsets D's victory over A. (A complex cyclical graph would contain multiple, intersecting cycles and be a much bigger headache, but my hunch is that they are extremely rare.)

The third problem with using a network graph as a ranking mechanism is perhaps its biggest, if not mathematically, then for the debate community to stomach:


Notice the problem? There are no cycles; everything flows in only one direction. The rankings, according to the graph, are unambiguously {A, B, C, D, E, F}. Here it is again:


C beat D, but at any tournament, D would be ranked higher, because C is 1-2 and D is 2-1. In the situation I graphed, C is the better team but had a tougher schedule. (It's also possible to create an example in which D is the better team but just had an off-round or a crazy judge.) There's no cycle in the graph, so there's no need to have an upset, but I believe every debater and coach would say D should be ranked higher. Total wins as the first method of ranking is sacrosanct to the debate community, and with good reason. Total wins is clear and unambiguous; a network graph is abstract and complex. I know I would never want a tournament to start interpreting results with a network graph; it would create too much room for error when deciding breaks.

This last problem is insurmountable. I think the lesson is that we need to take every effort to make schedule strength more equitable, but there's no mathematical way to jigger results to somehow weight or re-interpret an unfair set of pairings. The cat's out of the bag, and we just have to say, "Sorry, tournaments aren't always fair," at that point. The bottom line is that network graphs will never and ought not be used for tournament rankings. But there's is an alternative use for graph theory: as a tiebreaker at round robins.

Let's say a six-team round robin has these final results:

Team Record
A 4-1
B 3-2
C 3-2
D 3-2
E 2-3
F 0-5

There's a three-way tie for second place. My suggestion is that round robins can use an idea from graph theory as the first tiebreaker, before resorting to speaker points. I believe that direct results ought to be respected as much as possible, and in round robins, you have direct results for every head-to-head match up. Who cares that team C spoke prettier than B or D if C lost both of those rounds? Here's the graph of this hypothetical round robin:


Now, you may notice that C beat A, which suggests that C is the best of the three, or you may focus on the fact that D beat both B and C, which suggests that D is the best. Both may catch your eye, but there's a way to quantify an exact result. But first, you need to turn the graph into an adjacency matrix, like so:


A column represents a team's wins; a row, its losses. Hence, reading down column A, you see that team A beat B, D, E, and F; reading across column A, you see that team A lost to C. The adjacency matrix contains all the information that the graph does; it's merely another representation of the same data. You might also notice that there's an easy way to double-check the matrix:


You can add to make sure you have the right number of wins in the column and losses in the row for each team. (The adjacency matrix is easy to do for multi-ballot round robins; just put the ballots won into the correct spot for each team.)

Now, we need to test possible rankings. There are six possibilities created by the three-way tie: {A, B, C, D, E, F}, {A, B, D, C, E, F}, {A, C, B, D, E, F}, {A, C, D, B, E, F}, {A, D, B, C, E, F}, and {A, D, C, B, E, F}. We create an adjacency matrix for each possible ranking, a matrix of the hypothetical results that perfectly consistent the ranking order with no upsets, ties, or ambiguity. For example, for the possible ranking {A, B, C, D, E, F}, the matrix is:


The matrix shows results that would be perfectly consistent with the ranking. Now we can calculate a score for how well this ranking corresponds to the actual tournament results:


Subtract the possible ranking matrix [R] from the actual tournament results [T] and count the -1s. (You can count the +1s also; they are symmetrical.) According to this ranking, there were four "upsets": that C actually beat A, that D actually beat B, that D actually beat C, and that E actually beat D. If a tournament accepts the ranking {A, B, C, D, E, F}, it "overturns" four direct results.

How do the other rankings compare? Using the same method for each "prediction," the rankings can be compared:

Rank order "Upsets"
{A, B, C, D, E, F} 4
{A, B, D, C, E, F} 3
{A, C, B, D, E, F} 5
{A, C, D, B, E, F} 4
{A, D, B, C, E, F} 2
{A, D, C, B, E, F} 3

The best ranking is obviously {A, D, B, C, E, F}. It upsets the fewest direct results. In fact, the two that are upset make perfect sense:


that C (3-2) actually beat A (4-1) and that E (2-3) actually beat D (3-2). In a sense, these were unavoidable (or you might even say real) upsets, not artifacts created by a poor ranking. Anyway, the point is, the three-way tie could be broken in this case without resorting to speaker points. This algorithm would be relatively easy to program into a tab program for round robins.

Of course, some ties are cannot be resolved by this method, namely, if the ties are really contradictions created by cycles. There's still a place for speaker points and other tiebreakers.